Biomedical Information Extraction
113 items from caufieldjh/awesome-bioie ★468
-
UMLS Semantic Network semanticnetwork.nlm.nih.gov
paper - Lists of 133 semantic types and 54 semantic relationships covering biomedical concepts and vocabulary. Is the Metathesaurus too complex for your needs? Try this. Does not require UTS account to download.
-
This paper from Hongfang Liu's group at Mayo Clinic sciencedirect.com
demonstrates how text embeddings trained on biomedical or clinical text can, but don't always, perform better on biomedical natural language processing tasks. That being said, pre-trained embeddings may be appropriate for your needs, especially as training domain-specific…
-
Clinical information extraction applications: A literature review sciencedirect.com
A review of clinical IE papers published as of September 2016. From Mayo Clinic group (see below).
-
Literature Based Discovery: Models, methods, and trends sciencedirect.com
A review of Literature Based Discovery (LBD), or the philosophy that meaningful connections may be found between seemingly unrelated scientific literature.
-
JBI sciencedirect.com
The Journal of Biomedical Informatics. Not open access by default, though it does have an open-access "X" version.
-
UTHealth Houston Biomedical Natural Language Processing Lab sbmi.uth.edu
Based in the University of Texas Health Science Center at Houston, School of Biomedical Informatics and led by Dr. Hua Xu.
-
BioScope rgai.inf.u-szeged.hu
paper - a corpus of sentences from medical and biological documents, annotated for negation, speculation, and linguistic scope.
-
PSB psb.stanford.edu
The Pacific Symposium on Biocomputing.
-
n2c2 (formerly i2b2) Data portal.dbmi.hms.harvard.edu
The Department of Biomedical Informatics (DBMI) at Harvard Medical School manages data for the National NLP Clinical Challenges and the Informatics for Integrating Biology and the Bedside challenges running since 2006. They require registration before access and use. Datasets…
-
MIMIC-CXR physionet.org
The MIMIC Chest X-Ray database. Contains more than 377,000 radiographic images and accompanying free-text radiology reports. As with MIMIC-III, requires acceptance of a data use agreement.
-
MedTator ohnlp.github.io
paper - code - An annotation tool designed to have minimal dependencies.
-
VCU Natural Language Processing Lab nlp.cs.vcu.edu
Based at Virginia Commonwealth University and led by Dr. Bridget McInnes.
-
RxNorm nlm.nih.gov
paper - Normalized names for clinical drugs and drug packs, with combined ingredients, strengths, and form, and assigned types from the Semantic Network (see below). Released monthly.
-
UMLS Knowledge Sources nlm.nih.gov
reference manual - A large and comprehensive collection of biomedical terminology and identifiers, as well as accompanying tools and scripts. Depending on your purposes, the single file MRCONSO.RRF may be sufficient, as this file contains unique identifiers and names for all…
-
UMLS Metathesaurus nlm.nih.gov
paper - Mappings between >3.8 million concepts, 14 million concept names, and >200 sources of biomedical vocabulary and identifiers. It's big. It may help to prepare a subset of the Metathesaurus with the MetamorphoSys installation tool but we're still talking about ~30 Gb of…
-
Clinical Questions Collection nlm.nih.gov
also known as CQC or the Iowa collection, these are several thousand questions posed by physicians during office visits along with the associated answers.
-
PubTator Central ncbi.nlm.nih.gov
paper - A web platform that identifies five different types of biomedical concepts in PubMed articles and PubMed Central full texts. The full annotation sets are downloadable (see Annotated Text Data below).
-
TaggerOne ncbi.nlm.nih.gov
paper - Performs concept normalization (see also DNorm above). Can be trained for specific concept types and can perform NER independent of other normalization functions.
-
DNorm ncbi.nlm.nih.gov
paper - A method for disease normalization, i.e., linking mentions of disease names and acronyms to unique concept identifiers. Downloadable version includes the NCBI Disease Corpus and BC5CDR (see Annotated Text Data below).
-
BioNLP group at NCBI ncbi.nlm.nih.gov
Develops improvements to biomedical literature search and curation (e.g., through PubMed), led by Dr. Zhiyong Lu.
-
PubMed Central Open Access Subset ncbi.nlm.nih.gov
A set of PubMed Central articles usable under licenses other than traditional copyright, though the exact licenses vary by publication and source. Articles are available as PDF and XML.
-
Capturing the Patient's Perspective: a Review of Advances in Natural Language Processing of Health-Related Text ncbi.nlm.nih.gov
A 2017 review of natural language processing methods applied to information extraction in health records and social media text. An important note from this review: "One of the main challenges in the field is the availability of data that can be shared and which can be used by…
-
NCBI Disease Corpus ncbi.nlm.nih.gov
paper - A corpus of 793 biomedical abstracts annotated with names of diseases and related concepts from MeSH and OMIM.
-
Scientific Data nature.com
An open-access Springer Nature journal publishing "descriptions of scientifically valuable datasets, and research that advances the sharing and reuse of scientific data".
-
National Centre for Text Mining (NaCTeM) nactem.ac.uk
Based at the University of Manchester and led by Prof. Sophia Ananiadou, NaCTeM is concerned with text mining in general but has a particular focus on biomedical applications.
-
Monarch Initiative monarchinitiative.org
A joint effort between groups at Oregon State University, Oregon Health & Science University, Lawrence Berkeley National Lab, The Jackson Laboratory, and several others, seeking to "integrate biological information using semantics, and present it in a novel way, leveraging…
-
MIMIC-III mimic.physionet.org
paper - Deidentified health data from ~60,000 intensive care unit admissions. Requires completion of an online training course (CITI training) and acceptance of a data use agreement prior to use.
-
MIMIC-IV mimic-iv.mit.edu
An update to MIMIC-III's multimodal patient data, now covering more recent years of admissions, plus a new data structure, emergency department records, and links to MIMIC-CXR images.
-
PubMedBERT microsoft.github.io
paper - A BERT model trained from scratch on PubMed, with versions trained on abstracts+full texts and on abstracts alone.
-
Med7 medium.com
paper - code - a Python package and model (for use with spaCy) for doing NER with medication-related concepts.
-
Mayo Clinic's clinical natural language processing program mayo.edu
Several groups at Mayo Clinic have made major contributions to BioIE (for example, the Apache cTAKES platform) over the past 20 years.
-
Biomedical Literature Mining link.springer.com
A (non-free) volume of Methods in Molecular Biology from 2014. Chapters covers introductory principles in text mining, applications in the biological sciences, and potential for use in clinical or medical safety scenarios.
-
Demner-Fushman group at NLM lhncbc.nlm.nih.gov
-
SPECIALIST Lexicon lexsrv3.nlm.nih.gov
paper - A general English lexicon that includes many biomedical terms. Updated yearly since 1994 and still updated as of 2019. Part of UMLS but does not require UTS account to download.
-
eHealth-KD knowledge-learning.github.io
Challenges for encouraging "development of software technologies to automatically extract a large variety of knowledge from eHealth documents written in the Spanish Language". Previously held as part of TASS, an annual workshop for semantic analysis in Spanish.
-
Undiscovered Public Knowledge jstor.org
(paywalled) and Rediscovering Don Swanson: the Past, Present and Future of Literature-Based Discovery.
-
Getting Started in Text Mining journals.plos.org
A brief introduction to bio-text mining from Cohen and Hunter. More than ten years old but still quite relevant. See also an earlier paper by the same authors.
-
JensenLab text mining exercises jensenlab.org
-
JensenLab jensenlab.org
Based at the Novo Nordisk Foundation Center for Protein Research at the University of Copenhagen, Denmark.
-
ISMB iscb.org
The International Conference on Intelligent Systems for Molecular Biology is an annual conference hosted by the International Society for Computational Biology since 1993. Much of its focus has concerned bioinformatics and computational biology without an explicit clinical…
-
IMIA imia-medinfo.org
The International Medical Informatics Association. Publishes the IMIA Yearbook of Medical Informatics.
-
BIBM ieeebibm.org
The IEEE International Conference on Bioinformatics and Biomedicine.
-
Flair embeddings from PubMed github.com
A language model available through the Flair framework and embedding method. Trained over a 5% sample of PubMed abstracts until 2015, or > 1.2 million abstracts in total.
-
BioRED ftp.ncbi.nlm.nih.gov
paper - a set of >6.5K biomedical relation annotations, plus labels for novel findings.
-
BioWordVec figshare.com
paper - code - Word embeddings derived from biomedical text (>27 million PubMed titles and abstracts), including subword embedding model based on MeSH.
-
eICU Collaborative Research Database eicu-crd.mit.edu
paper - a database of observations from more than 200 thousand intensive care unit admissions, with consistent structure. Requires registration, training course completion, and data use agreement.
-
On the Dangers of Stochastic Parrots: Can Language Models Be Too Big? 🦜 dx.doi.org
a frequently referenced but still relevant work concerning the roles, applications, and risks of language models.
-
Large language models in healthcare: A comprehensive benchmark dx.doi.org
a statistical and human evaluation of sixteen different LLMs applied to medical language tasks.
-
Assessing the research landscape and clinical utility of large language models: a scoping review doi.org
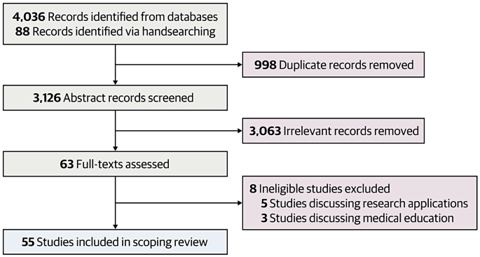
a high-level review of LLM applications in medicine as of March 2024.
-
Ethical and regulatory challenges of large language models in medicine doi.org
a review of ethical issues arising from applications of LLMs in biomedicine.
- next page of items loading…