Big Data
1,992 items in 9 lists
-
Apache Livy (incubating) livy.incubator.apache.org
The REST Spark Server.
-
Apache Kudu kudu.apache.org
Hadoop's storage layer to enable fast analytics on fast data.
-
Apache Knox Gateway knox.apache.org
single point of secure access for Hadoop clusters.
-
Kite Software Development Kit kitesdk.org
High-level data layer for Hadoop/HBase.
-
Apache Ignite ignite.apache.org
High-performance, integrated and distributed in-memory platform for computing and transacting on large-scale data sets in real-time, orders of magnitude faster than possible with traditional disk-based or flash technologies.
-
Apache Hadoop hadoop.apache.org
framework for distributed processing. Integrates MapReduce (parallel processing), YARN (job scheduling) and HDFS (distributed file system).
-
Apache Flume flume.apache.org
service to manage large amount of log data.
-
Apache Falcon falcon.apache.org
data management framework.
-
How to monitor Hadoop metrics datadoghq.com
Guide to monitoring Hadoop, with an overview of Hadoop architecture, and native methods for metrics collection.
-
Apache Curator curator.apache.org
Java libraries for Apache ZooKeeper.
-
Apache Crunch crunch.apache.org
a simple Java API for tasks like joining and data aggregation that are tedious to implement on plain MapReduce.
-
Lingual cascading.org
SQL-like query language for Cascading.
-
Apache Bigtop bigtop.apache.org
system deployment framework for the Hadoop ecosystem.
-
Big Data Benchmark amplab.cs.berkeley.edu
Benchmark of Redshift, Hive, Shark, Impala and Stiger/Tez.
-
Apache Accumulo accumulo.apache.org
distributed key/value store, built on Hadoop.
-
Apache SINGA - A General Distributed Deep Learning Platform singa.incubator.apache.org
-
Jupyter Notebook jupyter.org
Notebook and project application for interactive data science and scientific computing across all programming languages.
-
DexPaprika API api.dexpaprika.com
DEX pool, token, OHLCV, and trade data via API and MCP. Keyless access has rate and usage limits; see plans.
-
Spark Machine Learning spark.apache.org
Spark’s ML library consisting of common learning algorithms and utilities.
-
Cube square.github.io
uses MongoDB to store time series data.
-
The Analytics Engineering Podcast roundup.getdbt.com
How analytics engineers build and maintain data pipelines at scale.
-
NetworkX networkx.org
-
Data Analysis with Python and PySpark manning.com
Early Access
-
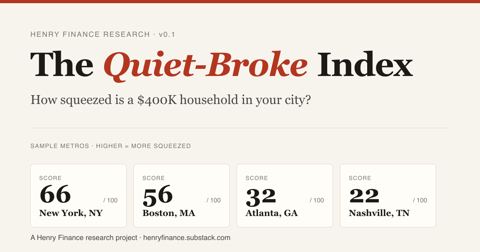
The Quiet-Broke Index jeevesagency.github.io
A 30-metro composite ranking of how much of a $400K household income gets consumed by housing, taxes, childcare, healthcare, and transport. Open methodology, free, no email gate.
-
enigma.com enigma.com
Navigate the world of public data - Quickly search and analyze billions of public records published by governments, companies and organizations.
-
Data Engineering Podcast dataengineeringpodcast.com
The show about modern data infrastructure.
-
DataDriven - SQL, Python, and Data Modeling Interview Questions datadriven.io
Interview practice with SQL query execution, Python, and data modeling exercises.
-
graphlab-create turi.com
A machine learning platform that enables data scientists and app developers to easily create intelligent apps at scale.
-
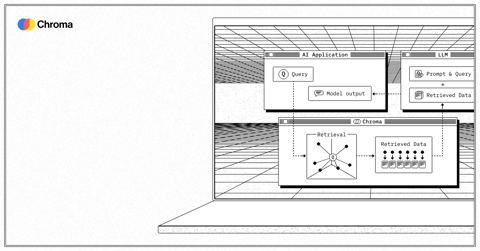
Chroma trychroma.com
open-source embedding database for AI applications.
-
Samoa samoa.incubator.apache.org
distributed streaming machine learning framework.
-
Qdrant qdrant.tech
vector database and similarity search engine with REST, gRPC, and client SDKs.
-
igraph igraph.org
-
igraph igraph.org
-
Weka cs.waikato.ac.nz
suite of machine learning software.
-
Chain of Thought chainofthought.show
Interviews with AI and data infrastructure leaders on building production systems.
-
recharts recharts.org
Redefined chart library built with React and D3
-
statnet statnet.org
-
networkD3 christophergandrud.github.io
-
Cascalog cascalog.org
data processing and querying library.
-
RocksDB rocksdb.org
embeddable persistent key-value store for fast storage based on LevelDB.
-
InfluxDB influxdata.com
a time series database with optimised IO and queries, supports pgsql and influx wire protocols.
-
graph-tool graph-tool.skewed.de
an efficient Python module for manipulation and statistical analysis of graphs (a.k.a. networks).
-
Hevo hevodata.com
No-code, fully automated data pipeline platform that supports extensive integrations, simplifying complex data workflows.
-
Glue aws.amazon.com
serverless fully managed extract, transform, and load (ETL) service
-
H2O h2o.ai
Fast statistical, machine learning & math runtime.
-
RancherOS rancher.com
RancherOS is a tiny Linux distro that runs the entire OS as Docker containers.
-
networkdiffusion github.com
-
crdt-merge github.com
Conflict-free merge for DataFrames, JSON, ML models & distributed agents — powered by CRDTs.
-
PFC-JSONL github.com
Specialized JSONL log compressor with block-level timestamp indexing and DuckDB integration. Achieves ~9% compression ratio (better than gzip) with time-range random access queries.
-
ContentStructure github.com
- next page of items loading…