Big Data
1,992 items in 9 lists
-
CCAS github.com
-
GraphVisualize.jl github.com
-
-
https://github.com/lovelysystems/ls-hive github.com
-
https://github.com/hrp/sequel-hive-adapter github.com
-
-
GraphCentrality.jl github.com
-
Aegis DQ github.com
Open-source agentic data quality framework with LLM-powered diagnosis, root-cause analysis, SQL auto-fix proposals, and 31 rule types — DuckDB, Postgres, BigQuery, Databricks, Athena, Snowflake.
-
parag github.com
-
Networks.jl github.com
-
NetworkFlows.jl github.com
-
Estuary Benchmark Report github.com
reproducible, vendor-neutral data warehouse benchmark.
-
DataSpoc Pipe github.com
Data ingestion engine that connects 400+ Singer taps to Parquet files in cloud buckets (S3, GCS, Azure). Streaming, incremental, with auto-catalog.
-
Smile.jl github.com
-
A tutorial for network centrality in R github.com
-
gdMetriX github.com
-
spark-connect-csharp github.com
C# bindings.
-
CARQ github.com
Context-Aware RAG Processing Queue for high availability and adaptive rate-limiting.
-
Signals CLI github.com
Intent signal monitoring CLI. Track LinkedIn engagers, keyword posters, job changers, funding events. JSON output for data pipelines.
-
Mindweave Synthetic Business Data github.com
42-table synthetic SME dataset with double-entry accounting, tax compliance (AU/US/UK), and temporal realism. CSV, SQL, Parquet, SQLite. Ideal for ETL pipeline testing.
-
db2lake github.com
Lightweight Node.js ETL framework for databases → data lakes/warehouses.
-
Mixer github.com
-
Lambdo github.com
Lambdo is a workflow engine which significantly simplifies the analysis process by unifying feature engineering and machine learning operations.
-
Zoomdata zoomdata.com
Big Data Analytics.
-
Ice Bucket Challenge Data Visualization youtube.com
-
-
Designing Data Visualizations with Noah Iliinsky youtube.com
-
The beauty of data visualization youtube.com
-
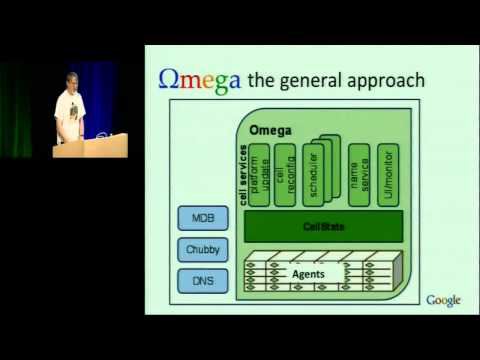
Google Omega youtube.com
job scheduling and monitoring system.
-
Yahoo Gridmix3 yahoohadoop.tumblr.com
Hadoop cluster benchmarking from Yahoo engineer team.
-
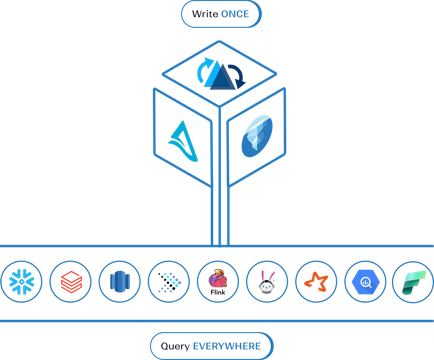
Apache XTable xtable.apache.org
incubating Apache project for interoperability across lakehouse table formats.
-
RecDB www-users.cs.umn.edu
Open Source Recommendation Engine Built Entirely Inside PostgreSQL.
-
IBM Netezza www-01.ibm.com
high-performance data warehouse appliances.
-
Google Borg wired.com
job scheduling and monitoring system.
-
Facebook Prism wired.com
multi datacenters replication system.
-
Trafodion wiki.trafodion.org
enterprise-class SQL-on-HBase solution targeting big data transactional or operational workloads.
-
Lustre file system wiki.lustre.org
high-performance distributed filesystem.
-
Apache MapReduce wiki.apache.org
programming model for processing large data sets with a parallel, distributed algorithm on a cluster.
-
Apache Whirr whirr.apache.org
set of libraries for running cloud services.
-
WebScaleSQL webscalesql.org
is a collaboration among engineers from several companies that face similar challenges in running MySQL at scale.
-
WebDataRocks webdatarocks.com
free web pivot table component for embedding analytics in applications.
-
Weaviate weaviate.io
open-source vector database for semantic search with structured filtering.
-
Wallaroo wallaroolabs.com
The ultrafast and elastic data processing engine. Big or fast data - no fuss, no Java needed.
-
Cheetah vldbarc.org
High Performance, Custom Data Warehouse on Top of MapReduce.
-
2015 vldb.org
Facebook - One Trillion Edges: Graph Processing at Facebook-Scale.
-
2012 vldb.org
Google - Processing a trillion cells per mouse click.
-
Vespa vespa.ai
is an engine for low-latency computation over large data sets. It stores and indexes your data such that queries, selection and processing over the data can be performed at serving time.
-
redpanda vectorized.io
A Kafka® replacement for mission critical systems; 10x faster. Written in C++.
-
Sibyl users.soe.ucsc.edu
System for Large Scale Machine Learning at Google.
-
2012 usenix.org
AMPLab - Fast and Interactive Analytics over Hadoop Data with Spark.
- next page of items loading…