SciBERT: A Pretrained Language Model for Scientific Text
EMNLP'19, 2019. [All Versions]. Searching and synthesizing scientific literature, aiding researchers in hypothesis generation, and assisting with experimental design, making scientific knowledge more accessible.
- from
- AGI & CoCoSci
- added
- 2026-10-10
- likes
- 0
similar
-
BioBERT: a pre-trained biomedical language representation model for biomedical text mining academic.oup.com
Bioinformatics, 2020. [All Versions]. Answering medical questions, identifying relevant clinical trials, and diagnosing diseases based on symptoms, making medical information more accessible to the general public.
-
-
CodeBERT: A Pre-Trained Model for Programming and Natural Languages aclanthology.org
EMNLP'20, 2020. [All Versions]. Completing code, generating programming documentation, and providing technical support, making programming knowledge more accessible to non-experts.
-
BioBERT github.com
paper - code - A PubMed and PubMed Central-trained version of the BERT language model.
-
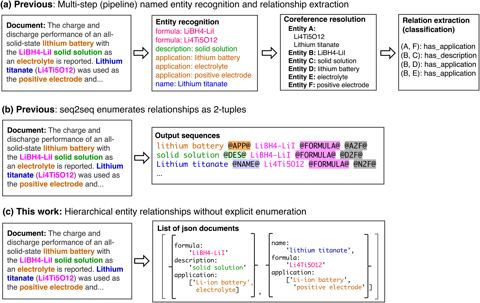
Structured information extraction from scientific text with large language models nature.com
Nature Communications, 2024. [All Versions]. This paper presents a simple approach to joint named entity recognition and relation extraction and demonstrate how pretrained large language models can be fine-tuned to extract useful records of complex scientific knowledge. The…
-
AGI & CoCoSci › Papers > Science Logology > AI Assisted Research: “EMNLP'19, 2019. [All Versions]. Searching and synthesizing scientific literature, aiding researchers in hypothesis generation, and assisting with experimental design, making scientific knowledge more accessible.”