Data Engineering
313 items from igorbarinov/awesome-data-engineering ★9,166
-
Spark GraphX spark.apache.org
Apache Spark's API for graphs and graph-parallel computation.
-
Redis redis.io
An open source, BSD licensed, advanced key-value cache and store.
-
rawquery rawquery.dev
Managed lakehouse platform on Apache Iceberg with DuckDB query compute, S3 storage, Postgres wire protocol, and SQL transforms.
-
RavenDB ravendb.net
Fully Transactional NoSQL Document Database.
-
RabbitMQ rabbitmq.com
Robust messaging for applications.
-
PyQtGraph pyqtgraph.org
A pure-python graphics and GUI library built on PyQt4 / PySide and numpy. It is intended for use in mathematics / scientific / engineering applications.
-
Apache Pulsar pulsar.apache.org
An open-source distributed pub-sub messaging system.
-
OrientDB orientdb.com
2nd Generation Distributed Graph Database with the flexibility of Documents in one product with an Open Source commercial friendly license.
-
OrangeFS orangefs.org
Orange File System is a branch of the Parallel Virtual File System.
-
MariaDB mariadb.org
An enhanced, drop-in replacement for MySQL.
-
Apache Hudi hudi.apache.org
An open source framework for managing storage for real time processing, one of the most interesting feature is the Upsert.
-
GreatExpectation greatexpectations.io
Open Source data validation framework to manage data quality. Users can define and document “expectations” rules about how data should look and behave.
-
GlusterFS gluster.org
Gluster Filesystem.
-
Rhombus github.com
A time-series object store for Cassandra that handles all the complexity of building wide row indexes.
-
Zilla github.com
- An API gateway built for event-driven architectures and streaming that supports standard protocols such as HTTP, SSE, gRPC, MQTT, and the native Kafka protocol.
-
GitHub Archive gharchive.org
GitHub's public timeline since 2011, updated every hour.
-
Estuary Flow estuary.dev
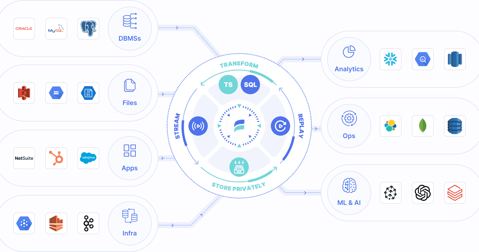
No/low-code data pipeline platform that handles both batch and real-time data ingestion.
-
Embulk embulk.org
An open source bulk data loader that helps data transfer between various databases, storages, file formats, and cloud services.
-
YData Profiling docs.profiling.ydata.ai
A general-purpose open-source data profiler for high-level analysis of a dataset.
-
DataRaven dataraven.io
Managed cloud object storage transfers for ingestion workflows.
-
Riak-TS basho.com
Riak TS is the only enterprise-grade NoSQL time series database optimized specifically for IoT and Time Series data.
-
AWS EMR aws.amazon.com
A web service that makes it easy to quickly and cost-effectively process vast amounts of data.
-
ArcadeDB arcadedb.com
Open-source multi-model database with native graph, document, key-value, and vector support. SQL, Cypher, and Gremlin query languages. Apache 2.0 license.
-
Alluxio alluxio.org
A memory-centric distributed storage system enabling reliable data sharing at memory-speed across cluster frameworks, such as Spark and MapReduce.
-
Apache Spark spark.apache.org
Makes it easy to build scalable fault-tolerant streaming applications.
-
Spark Packages spark-packages.org
A community index of packages for Apache Spark.
-
Apache Livy (incubating) livy.incubator.apache.org
The REST Spark Server.
-
DexPaprika API api.dexpaprika.com
DEX pool, token, OHLCV, and trade data via API and MCP. Keyless access has rate and usage limits; see plans.
-
The Analytics Engineering Podcast roundup.getdbt.com
How analytics engineers build and maintain data pipelines at scale.
-
The Quiet-Broke Index jeevesagency.github.io
A 30-metro composite ranking of how much of a $400K household income gets consumed by housing, taxes, childcare, healthcare, and transport. Open methodology, free, no email gate.
-
Data Engineering Podcast dataengineeringpodcast.com
The show about modern data infrastructure.
-
DataDriven - SQL, Python, and Data Modeling Interview Questions datadriven.io
Interview practice with SQL query execution, Python, and data modeling exercises.
-
graphlab-create turi.com
A machine learning platform that enables data scientists and app developers to easily create intelligent apps at scale.
-
Chain of Thought chainofthought.show
Interviews with AI and data infrastructure leaders on building production systems.
-
H2O h2o.ai
Fast statistical, machine learning & math runtime.
-
RancherOS rancher.com
RancherOS is a tiny Linux distro that runs the entire OS as Docker containers.
-
crdt-merge github.com
Conflict-free merge for DataFrames, JSON, ML models & distributed agents — powered by CRDTs.
-
PFC-JSONL github.com
Specialized JSONL log compressor with block-level timestamp indexing and DuckDB integration. Achieves ~9% compression ratio (better than gzip) with time-range random access queries.
-
Aegis DQ github.com
Open-source agentic data quality framework with LLM-powered diagnosis, root-cause analysis, SQL auto-fix proposals, and 31 rule types — DuckDB, Postgres, BigQuery, Databricks, Athena, Snowflake.
-
DataSpoc Pipe github.com
Data ingestion engine that connects 400+ Singer taps to Parquet files in cloud buckets (S3, GCS, Azure). Streaming, incremental, with auto-catalog.
-
CARQ github.com
Context-Aware RAG Processing Queue for high availability and adaptive rate-limiting.
-
Signals CLI github.com
Intent signal monitoring CLI. Track LinkedIn engagers, keyword posters, job changers, funding events. JSON output for data pipelines.
-
Mindweave Synthetic Business Data github.com
42-table synthetic SME dataset with double-entry accounting, tax compliance (AU/US/UK), and temporal realism. CSV, SQL, Parquet, SQLite. Ideal for ETL pipeline testing.
-
db2lake github.com
Lightweight Node.js ETL framework for databases → data lakes/warehouses.
-
PigZ zlib.net
A parallel implementation of gzip for modern multi-processor, multi-core machines.
-
Zingg zingg.ai
Open source Master Data Management platform using machine learning for entity resolution at scale. Native to Databricks, Microsoft Fabric, Snowflake, AWS, and GCP. Golden records are maintained through a persistent Zingg ID across all systems and sources.
-
XtreemFS xtreemfs.org
Fault-tolerant distributed file system for all storage needs.
-
Xquik xquik.com
Real-time X (Twitter) data extraction platform with REST API (76 endpoints), 20 bulk extraction tools, account monitoring, HMAC-signed webhooks, and MCP server for AI agent integration.
-
SequenceFile wiki.apache.org
A flat file consisting of binary key/value pairs. It is extensively used in MapReduce as input/output formats.
-
Titan titan.thinkaurelius.com
A scalable graph database optimized for storing and querying graphs containing hundreds of billions of vertices and edges distributed across a multi-machine cluster.
- next page of items loading…