Data Engineering
313 items from igorbarinov/awesome-data-engineering ★9,166
-
Apache Oozie oozie.apache.org
A workflow scheduler system to manage Apache Hadoop jobs.
-
Apache NiFi nifi.apache.org
An easy to use, powerful, and reliable system to process and distribute data.
-
Apache Mahout mahout.apache.org
An environment for quickly creating scalable performant machine learning applications.
-
Apache Hive hive.apache.org
Data warehouse software facilitates querying and managing large datasets residing in distributed storage.
-
Apache HBase hbase.apache.org
The Hadoop database, a distributed, scalable, big data store.
-
Apache Drill drill.apache.org
Schema-free SQL Query Engine for Hadoop, NoSQL and Cloud Storage.
-
Cascading cascading.org
Java based application development platform.
-
Azkaban azkaban.github.io
A batch workflow job scheduler created at LinkedIn to run Hadoop jobs. Azkaban resolves the ordering through job dependencies and provides an easy-to-use web user interface to maintain and track your workflows.
-
d3plus d3plus.org
D3's simpler, easier to use cousin. Mostly predefined templates that you can just plug data in.
-
QuestDB questdb.io
A relational column-oriented database designed for real-time analytics on time series and event data.
-
DuckDB duckdb.org
in-process SQL OLAP Database Management System. [MIT] website
-
Simple Storage Service (S3) aws.amazon.com
Object storage built to retrieve any amount of data from anywhere.
-
Redshift aws.amazon.com
A fast, fully managed, petabyte-scale data warehouse that makes it simple and cost-effective to analyze all your data using your existing business intelligence tools.
-
Relational Database Service (RDS) aws.amazon.com
Makes it easy to set up, operate, and scale a relational database in the cloud.
-
Kinesis aws.amazon.com
A fully managed, cloud-based service for real-time data processing over large, distributed data streams.
-
neo4j neo4j.com
The leading graph database!
-
VoltDB voltdb.com
An ACID-compliant RDBMS which uses a shared nothing architecture.
-
Vertica vertica.com
Distributed, MPP columnar database with extensive analytics SQL.
-
TimescaleDB timescale.com
Built as an extension on top of PostgreSQL, TimescaleDB is a time-series SQL database providing fast analytics, scalability, with automated data management on a proven storage engine.
-
Spark GraphX spark.apache.org
Apache Spark's API for graphs and graph-parallel computation.
-
Redis redis.io
An open source, BSD licensed, advanced key-value cache and store.
-
rawquery rawquery.dev
Managed lakehouse platform on Apache Iceberg with DuckDB query compute, S3 storage, Postgres wire protocol, and SQL transforms.
-
RavenDB ravendb.net
Fully Transactional NoSQL Document Database.
-
RabbitMQ rabbitmq.com
Robust messaging for applications.
-
PyQtGraph pyqtgraph.org
A pure-python graphics and GUI library built on PyQt4 / PySide and numpy. It is intended for use in mathematics / scientific / engineering applications.
-
Apache Pulsar pulsar.apache.org
An open-source distributed pub-sub messaging system.
-
OrientDB orientdb.com
2nd Generation Distributed Graph Database with the flexibility of Documents in one product with an Open Source commercial friendly license.
-
OrangeFS orangefs.org
Orange File System is a branch of the Parallel Virtual File System.
-
MariaDB mariadb.org
An enhanced, drop-in replacement for MySQL.
-
Apache Hudi hudi.apache.org
An open source framework for managing storage for real time processing, one of the most interesting feature is the Upsert.
-
GreatExpectation greatexpectations.io
Open Source data validation framework to manage data quality. Users can define and document “expectations” rules about how data should look and behave.
-
GlusterFS gluster.org
Gluster Filesystem.
-
GitHub Archive gharchive.org
GitHub's public timeline since 2011, updated every hour.
-
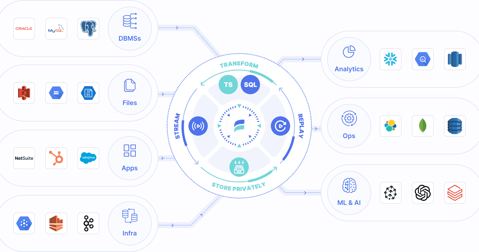
Estuary Flow estuary.dev
No/low-code data pipeline platform that handles both batch and real-time data ingestion.
-
Embulk embulk.org
An open source bulk data loader that helps data transfer between various databases, storages, file formats, and cloud services.
-
YData Profiling docs.profiling.ydata.ai
A general-purpose open-source data profiler for high-level analysis of a dataset.
-
DataRaven dataraven.io
Managed cloud object storage transfers for ingestion workflows.
-
Riak-TS basho.com
Riak TS is the only enterprise-grade NoSQL time series database optimized specifically for IoT and Time Series data.
-
AWS EMR aws.amazon.com
A web service that makes it easy to quickly and cost-effectively process vast amounts of data.
-
ArcadeDB arcadedb.com
Open-source multi-model database with native graph, document, key-value, and vector support. SQL, Cypher, and Gremlin query languages. Apache 2.0 license.
-
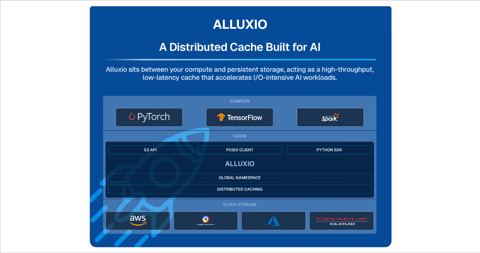
Alluxio alluxio.org
A memory-centric distributed storage system enabling reliable data sharing at memory-speed across cluster frameworks, such as Spark and MapReduce.
-
Apache Spark spark.apache.org
Makes it easy to build scalable fault-tolerant streaming applications.
-
Spark Packages spark-packages.org
A community index of packages for Apache Spark.
-
Apache Livy (incubating) livy.incubator.apache.org
The REST Spark Server.
-
DexPaprika API api.dexpaprika.com
DEX pool, token, OHLCV, and trade data via API and MCP. Keyless access has rate and usage limits; see plans.
-
The Analytics Engineering Podcast roundup.getdbt.com
How analytics engineers build and maintain data pipelines at scale.
-
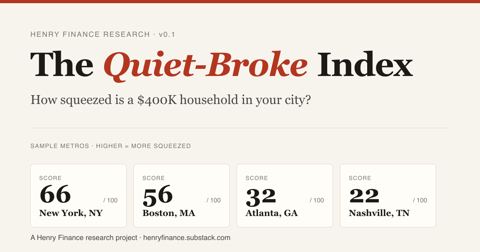
The Quiet-Broke Index jeevesagency.github.io
A 30-metro composite ranking of how much of a $400K household income gets consumed by housing, taxes, childcare, healthcare, and transport. Open methodology, free, no email gate.
-
Data Engineering Podcast dataengineeringpodcast.com
The show about modern data infrastructure.
-
DataDriven - SQL, Python, and Data Modeling Interview Questions datadriven.io
Interview practice with SQL query execution, Python, and data modeling exercises.
-
graphlab-create turi.com
A machine learning platform that enables data scientists and app developers to easily create intelligent apps at scale.
- next page of items loading…