Code Points
46 items from codepoints/awesome-codepoints ★778
-
U+1F574 codepoints.net
MAN IN BUSINESS SUIT LEVITATING - A rather curious character, that only made it into Unicode for its appearance in the Webdings font (for reasons of backwards compatibility).
-
U+1F4C0 codepoints.net
DVD - only code point name without any vowel (source)
-
U+1F402 codepoints.net
OX - shortest name.
-
U+1F3FB to U+1F3FF codepoints.net
. They are called “Emoji Modifier Fitzpatrick Type” 1 to 6, with 1 the palest and 6 the darkest. If one of these characters follows an emoji, that emoji is meant to be rendered in the appropriate skin color of the Fitzpatrick scale. If no such modifier is added, the skin tone…
-
Regional Indicator Symbols codepoints.net
U+1F1E6 to U+1F1FF resemble the 26 latin characters. They are used to create flag emoji. Since the Unicode consortium didn’t feel like getting on board with international politics, the solution to flags is to combine these 26 characters to the respective ISO code for a country…
-
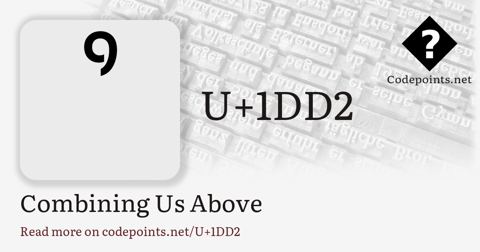
U+1DD2 codepoints.net
COMBINING US ABOVE - this is the most romantic code point.
-
U+1D455 codepoints.net
is missing. It would be an italic small “h”. It was not encoded, because it would be identical to the Planck constant ℎ (U+210E).
-
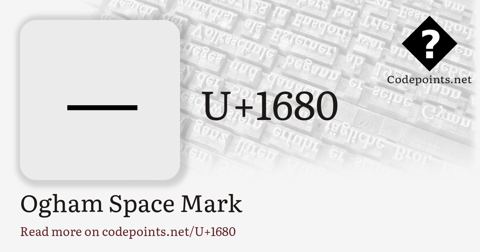
U+1680 codepoints.net
OGHAM SPACE MARK - a space that looks like a dash. Great to bring programmers close to madness: 1 + 2 === 3.
-
U+10FFFF codepoints.net
(non-character) - last code point. The whole rest of its plane apart from U+10FFFE, the code points in the 0x100000-0x10FFFD range, are private use characters, guaranteed to be never filled by a future Unicode standard.
-
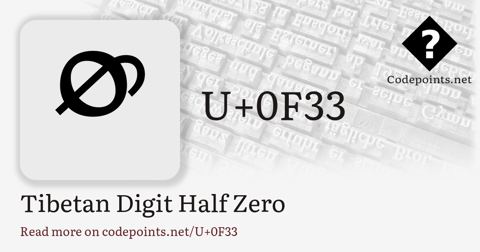
U+0F33 codepoints.net
TIBETAN DIGIT HALF ZERO - code point that represents the lowest “single-digit” number and at the same time the only negative one, -½.
-
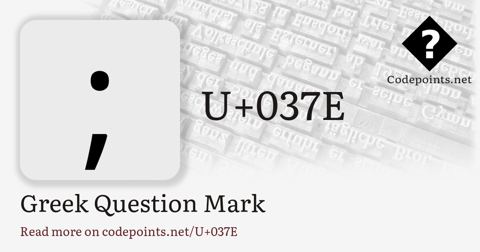
U+037E codepoints.net
GREEK QUESTION MARK - a look-alike to the semicolon. Also a fun way to annoy developers.
-
U+00AD codepoints.net
SOFT HYPHEN - (in HTML: ­) like ZERO WIDTH SPACE, but show a hyphen if (and only if) a break occurs.
-
U+00A0 codepoints.net
NO-BREAK SPACE - force adjacent characters to stick together. Well known as in HTML.
-
U+0080 codepoints.net
, U+0081 and U+0099. These so-called C1 control characters are more or less unspecified. They got into Unicode, because they were present in the very first version of what should later become ISO 10646, the ISO-standardized version of Unicode. They were meant to be part of an…
-
U+006F codepoints.net
LATIN SMALL LETTER O - leads the list of characters with confusable shapes. Of all the possible mappings in the list of confusable characters, the small “o” leads with a whopping 73 entries of similar looking glyphs, followed by U+006C LATIN SMALL LETTER L with 70 entries.
-
U+0000 codepoints.net
<control> - first code point.