Big Data
645 items from 0xnr/awesome-bigdata ★14,672
-
TimescaleDB timescale.com
Built as an extension on top of PostgreSQL, TimescaleDB is a time-series SQL database providing fast analytics, scalability, with automated data management on a proven storage engine.
-
Redis redis.io
An open source, BSD licensed, advanced key-value cache and store.
-
rawquery rawquery.dev
Managed lakehouse platform on Apache Iceberg with DuckDB query compute, S3 storage, Postgres wire protocol, and SQL transforms.
-
RavenDB ravendb.net
Fully Transactional NoSQL Document Database.
-
OrientDB orientdb.com
2nd Generation Distributed Graph Database with the flexibility of Documents in one product with an Open Source commercial friendly license.
-
MariaDB mariadb.org
An enhanced, drop-in replacement for MySQL.
-
Apache Hudi hudi.apache.org
An open source framework for managing storage for real time processing, one of the most interesting feature is the Upsert.
-
GreatExpectation greatexpectations.io
Open Source data validation framework to manage data quality. Users can define and document “expectations” rules about how data should look and behave.
-
GlusterFS gluster.org
Gluster Filesystem.
-
Rhombus github.com
A time-series object store for Cassandra that handles all the complexity of building wide row indexes.
-
Zilla github.com
- An API gateway built for event-driven architectures and streaming that supports standard protocols such as HTTP, SSE, gRPC, MQTT, and the native Kafka protocol.
-
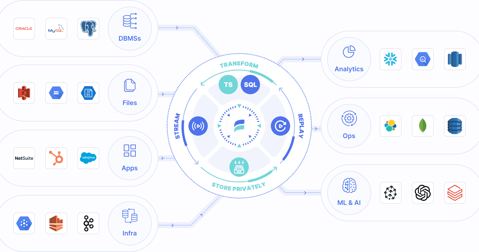
Estuary Flow estuary.dev
No/low-code data pipeline platform that handles both batch and real-time data ingestion.
-
Embulk embulk.org
An open source bulk data loader that helps data transfer between various databases, storages, file formats, and cloud services.
-
DataRaven dataraven.io
Managed cloud object storage transfers for ingestion workflows.
-
Akka Toolkit akka.io
runtime for distributed, and fault tolerant event-driven applications on the JVM.
-
Aerospike aerospike.com
NoSQL flash-optimized, in-memory. Open source and "Server code in 'C' (not Java or Erlang) precisely tuned to avoid context switching and memory copies."
-
Riak-TS basho.com
Riak TS is the only enterprise-grade NoSQL time series database optimized specifically for IoT and Time Series data.
-
ArcadeDB arcadedb.com
Open-source multi-model database with native graph, document, key-value, and vector support. SQL, Cypher, and Gremlin query languages. Apache 2.0 license.
-
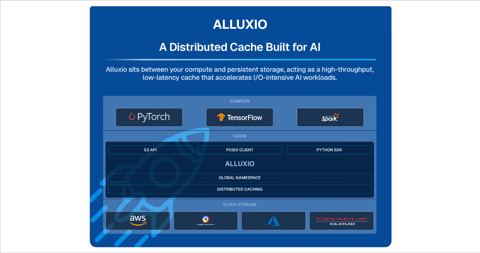
Alluxio alluxio.org
A memory-centric distributed storage system enabling reliable data sharing at memory-speed across cluster frameworks, such as Spark and MapReduce.
-
Ably ably.com
Pub/sub messaging platform for IoT
-
Apache Tajo tajo.apache.org
distributed data warehouse system on Hadoop.
-
Presto prestodb.io
distributed SQL query engine.
-
Apache Pig pig.apache.org
high level language to express data analysis programs for Hadoop.
-
Apache Nutch nutch.apache.org
open source web crawler.
-
Apache Kudu kudu.apache.org
Hadoop's storage layer to enable fast analytics on fast data.
-
Apache Knox Gateway knox.apache.org
single point of secure access for Hadoop clusters.
-
Apache Hadoop hadoop.apache.org
framework for distributed processing. Integrates MapReduce (parallel processing), YARN (job scheduling) and HDFS (distributed file system).
-
Apache Flume flume.apache.org
service to manage large amount of log data.
-
Apache Falcon falcon.apache.org
data management framework.
-
How to monitor Hadoop metrics datadoghq.com
Guide to monitoring Hadoop, with an overview of Hadoop architecture, and native methods for metrics collection.
-
Apache Curator curator.apache.org
Java libraries for Apache ZooKeeper.
-
Apache Crunch crunch.apache.org
a simple Java API for tasks like joining and data aggregation that are tedious to implement on plain MapReduce.
-
Lingual cascading.org
SQL-like query language for Cascading.
-
Apache Bigtop bigtop.apache.org
system deployment framework for the Hadoop ecosystem.
-
Big Data Benchmark amplab.cs.berkeley.edu
Benchmark of Redshift, Hive, Shark, Impala and Stiger/Tez.
-
Apache Accumulo accumulo.apache.org
distributed key/value store, built on Hadoop.
-
Jupyter Notebook jupyter.org
Notebook and project application for interactive data science and scientific computing across all programming languages.
-
Cube square.github.io
uses MongoDB to store time series data.
-
Data Analysis with Python and PySpark manning.com
Early Access
-
enigma.com enigma.com
Navigate the world of public data - Quickly search and analyze billions of public records published by governments, companies and organizations.
-
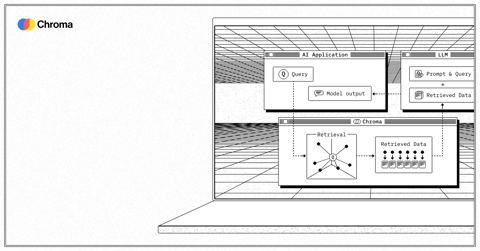
Chroma trychroma.com
open-source embedding database for AI applications.
-
Samoa samoa.incubator.apache.org
distributed streaming machine learning framework.
-
Qdrant qdrant.tech
vector database and similarity search engine with REST, gRPC, and client SDKs.
-
Weka cs.waikato.ac.nz
suite of machine learning software.
-
recharts recharts.org
Redefined chart library built with React and D3
-
Cascalog cascalog.org
data processing and querying library.
-
RocksDB rocksdb.org
embeddable persistent key-value store for fast storage based on LevelDB.
-
InfluxDB influxdata.com
a time series database with optimised IO and queries, supports pgsql and influx wire protocols.
-
Hevo hevodata.com
No-code, fully automated data pipeline platform that supports extensive integrations, simplifying complex data workflows.
-
Glue aws.amazon.com
serverless fully managed extract, transform, and load (ETL) service
- next page of items loading…