Big Data
1,992 items in 9 lists
-
Knowage knowage-suite.com
open source business intelligence platform. (former SpagoBi)
-
NoSQL Comparison kkovacs.eu
Cassandra vs MongoDB vs CouchDB vs Redis vs Riak vs HBase vs Couchbase vs Neo4j vs Hypertable vs ElasticSearch vs Accumulo vs VoltDB vs Scalaris comparison.
-
Kite kitesdk.org
is a set of libraries, tools, examples, and documentation focused on making it easier to build systems on top of the Hadoop ecosystem.
-
Apache Karaf karaf.apache.org
OSGi runtime that runs on top of any OSGi framework.
-
Jethrodata jethro.io
Interactive Big Data Analytics.
-
Jedox Palo jedox.com
customisable Business Intelligence platform.
-
Jaspersoft jaspersoft.com
powerful business intelligence suite.
-
PUMA Benchmarking issues.apache.org
benchmark suite for MapReduce applications.
-
intermix.io intermix.io
Performance Monitoring for Amazon Redshift
-
Facebook Apollo infoq.com
Facebook’s Paxos-like NoSQL database.
-
2014 infolab.stanford.edu
Stanford - Mining of Massive Datasets.
-
InfiniSQL infinisql.org
infinity scalable RDBMS.
-
Apache Twill incubator.apache.org
abstraction over YARN that reduces the complexity of developing distributed applications.
-
Apache Sentry incubator.apache.org
security module for data stored in Hadoop.
-
Apache S4 incubator.apache.org
framework for stream processing, implementation of S4.
-
Apache DataFu incubator.apache.org
collection of user-defined functions for Hadoop and Pig developed by LinkedIn.
-
Ignite ignite.apache.org
is an in-memory key-value data store providing full SQL-compliant data access that can optionally be backed by disk storage.
-
Apache Iceberg iceberg.apache.org
open table format for huge analytic datasets with schema evolution, hidden partitioning, and time travel.
-
IBM Streams ibm.com
platform for distributed processing and real-time analytics. Integrates with many of the popular technologies in the Big Data ecosystem (Kafka, HDFS, Spark, etc.)
-
Hypertable hypertable.org
column-oriented distributed datastore, inspired by BigTable.
-
H-Store hstore.cs.brown.edu
is an experimental main-memory, parallel database management system that is optimized for on-line transaction processing (OLTP) applications.
-
Stinger hortonworks.com
interactive query for Hive.
-
Apache YARN hortonworks.com
Cluster manager.
-
Hortonworks HOYA hortonworks.com
application that can deploy HBase cluster on YARN.
-
Hightouch hightouch.com
reverse ETL platform for syncing warehouse data into business applications.
-
ENCOG heatonresearch.com
machine learning framework that supports a variety of advanced algorithms, as well as support classes to normalize and process data.
-
SAP HANA hana.sap.com
is an in-memory, column-oriented, relational database management system.
-
Apache Hama hama.apache.org
BSP (Bulk Synchronous Parallel) computing framework.
-
Microsoft Azure Data Lake Store hadoop.apache.org
HDFS-compatible storage in Azure cloud
-
GridGain gridgain.com
GGFS, Hadoop compliant in-memory file system.
-
Graphite graphiteapp.org
scalable Realtime Graphing.
-
Google Dataflow googledevelopers.blogspot.it
create data pipelines to help them ingest, transform and analyze data.
-
Google Caffeine googleblog.blogspot.it
continuous indexing system.
-
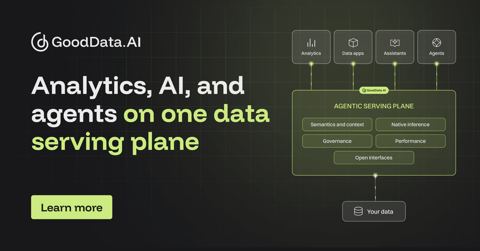
GoodData gooddata.com
platform for data products and embedded analytics.
-
Torch github.com
A deep learning library with a Lua API, supported by NYU and Facebook.
-
Theano github.com
A Python-focused machine learning library supported by the University of Montreal.
-
Berkeley SWIM Benchmark github.com
real-world big data workload benchmark.
-
LinkedIn Krati github.com
is a simple persistent data store with very low latency and high throughput.
-
Vowpal Wabbit github.com
learning system sponsored by Microsoft and Yahoo!.
-
Deeplearning4j github.com
Fast, open deep learning for the JVM (Java, Scala, Clojure). A neural network configuration layer powered by a C++ library. Uses Spark and Hadoop to train nets on multiple GPUs and CPUs.
-
Spark Catalyst github.com
is a Query Optimization Framework for Spark and Shark.
-
Gigasheet gigasheet.com
cloud spreadsheet for exploring and analyzing large datasets.
-
Pivotal GemFire XD gemfire.docs.pivotal.io
Low-latency, in-memory, distributed SQL data store. Provides SQL interface to in-memory table data, persistable in HDFS.
-
Apache Gearpump gearpump.github.io
real-time big data streaming engine based on Akka.
-
Frappe Charts frappe.io
GitHub-inspired simple and modern SVG charts for the web with zero dependencies.
-
FoundationDB foundationdb.com
distributed database, inspired by F1.
-
Flexmonster Pivot Table & Charts flexmonster.com
JavaScript component for pivot tables, charts, and web reporting.
-
Facebook Corona facebook.com
Hadoop enhancement which removes single point of failure.
-
Facebook Scuba facebook.com
distributed in-memory datastore.
-
Facebook Memcached facebook.com
fork of Memcache.
- next page of items loading…