Big Data
1,992 items in 9 lists
-
apache/spark hub.docker.com
Apache Spark Official Docker images.
-
SparkSQL databricks.com
Manipulating Structured Data Using Spark.
-
Spark with Scala Gitter channel gitter.im
"A place to discuss and ask questions about using Scala for Spark programming" started by @deanwampler.
-
Cytoscape cytoscape.github.io
JavaScript library for visualizing complex networks.
-
2008 cwiki.apache.org
AMPLab - Chukwa: A large-scale monitoring system.
-
Apache HCatalog cwiki.apache.org
table and storage management layer for Hadoop.
-
2009 cs.umd.edu
HadoopDB: An Architectural Hybrid of MapReduce and DBMS Technologies for Analytical Workloads.
-
Pydoop crs4.github.io
Python MapReduce and HDFS API for Hadoop.
-
jumboDB comsysto.github.io
document oriented datastore over Hadoop.
-
Comet comet.com
Comet provides an end-to-end model evaluation platform for AI developers, with best in class LLM evaluations, experiment tracking, and production monitoring.
-
JAQL code.google.com
declarative programming language for working with structured, semi-structured and unstructured data.
-
Facebook HydraBase code.facebook.com
evolution of HBase made by Facebook.
-
Cloudera Impala cloudera.com
framework for interactive analysis, Inspired by Dremel.
-
Google Cloud SQL cloud.google.com
MySQL databases in Google's cloud.
-
Google Cloud Datastore cloud.google.com
is a fully managed, schemaless database for storing non-relational data over BigTable.
-
Google BigQuery cloud.google.com
Google's cloud offering backed by their pioneering work on Dremel.
-
ClickHouse clickhouse.com
an open-source column-oriented database management system that allows generating analytical data reports in real time.
-
CitusDB citusdata.com
scales out PostgreSQL through sharding and replication.
-
IronDB circonus.com
scalable, general-purpose time series database.
-
Apache Chukwa chukwa.apache.org
data collection system.
-
Chronix chronix.io
a time series storage built to store time series highly compressed and for fast access times.
-
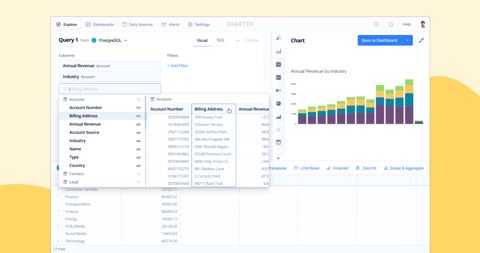
Chartio chartio.com
lean business intelligence platform to visualize and explore your data.
-
chartd chartd.co
responsive, retina-compatible charts with just an img tag.
-
Ceph Filesystem ceph.com
software storage platform designed.
-
Concurrent Pattern cascading.org
machine learning library for Cascading.
-
jupyter/docker-stacks/pyspark-notebook github.com
PySpark with Jupyter Notebook and Mesos client.
-
Fundamentals of Stream Processing: Application Design, Systems, and Analytics cambridge.org
This comprehensive, hands-on guide combining the fundamental building blocks and emerging research in stream processing is ideal for application designers, system builders, analytic developers, as well as students and researchers in the field.
-
Buildoop buildoop.github.io
Similar to Apache BigTop based on Groovy language.
-
Brooklyn brooklyncentral.github.io
library that simplifies application deployment and management.
-
Distributed Systems for fun and profit book.mixu.net
Theory of distributed systems. Include parts about time and ordering, replication and impossibility results.
-
Rackerlabs Blueflood blueflood.io
multi-tenant distributed metric processing system
-
HBase Coprocessor blogs.apache.org
implementation of Percolator, part of HBase.
-
Twitter TSAR blog.twitter.com
TimeSeries AggregatoR by Twitter.
-
Twitter Manhattan blog.twitter.com
real-time, multi-tenant distributed database for Twitter scale.
-
BIME Analytics bimeanalytics.com
business intelligence platform in the cloud.
-
Baidu Bigflow bigflow.cloud
an interface that allows for writing distributed computing programs providing lots of simple, flexible, powerful APIs to easily handle data of any scale.
-
BeeGFS beegfs.io
formerly FhGFS, parallel distributed file system.
-
Bedrock bedrockdb.com
a simple, modular, networked and distributed transaction layer built atop SQLite.
-
Microsoft Azure DocumentDB azure.microsoft.com
NoSQL cloud database service with protocol support for MongoDB
-
Apache Aurora aurora.apache.org
is a service scheduler that runs on top of Apache Mesos.
-
2012 arxiv.org
AMPLab - BlinkDB: Queries with Bounded Errors and Bounded Response Times on Very Large Data.
-
Apache APEX apex.apache.org
a unified, enterprise platform for big data stream and batch processing.
-
2013 amplab.cs.berkeley.edu
AMPLab - GraphX: A Resilient Distributed Graph System on Spark.
-
2012 amplab.cs.berkeley.edu
AMPLab - Blink and It’s Done: Interactive Queries on Very Large Data.
-
2013 amplab.cs.berkeley.edu
AMPLab - Presto: Distributed Machine Learning and Graph Processing with Sparse Matrices.
-
2013 amplab.cs.berkeley.edu
AMPLab - Shark: SQL and Rich Analytics at Scale.
-
Apache DataFu github.com
A library of general purpose functions and UDF's.
-
2013 amplab.cs.berkeley.edu
AMPLab - MLbase: A Distributed Machine-learning System.
-
2012 amplab.cs.berkeley.edu
AMPLab - Shark: Fast Data Analysis Using Coarse-grained Distributed Memory.
-
2011 amplab.cs.berkeley.edu
AMPLab - Scarlett: Coping with Skewed Popularity Content in MapReduce Clusters.
- next page of items loading…