Big Data
1,992 items in 9 lists
-
graphlab-create turi.com
A machine learning platform that enables data scientists and app developers to easily create intelligent apps at scale.
-
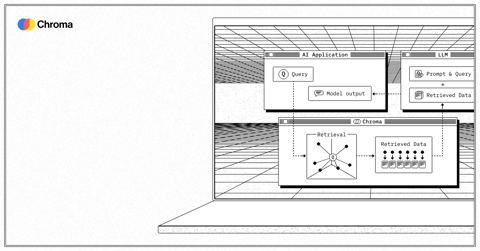
Chroma trychroma.com
open-source embedding database for AI applications.
-
Samoa samoa.incubator.apache.org
distributed streaming machine learning framework.
-
Qdrant qdrant.tech
vector database and similarity search engine with REST, gRPC, and client SDKs.
-
igraph igraph.org
-
igraph igraph.org
-
Weka cs.waikato.ac.nz
suite of machine learning software.
-
Chain of Thought chainofthought.show
Interviews with AI and data infrastructure leaders on building production systems.
-
recharts recharts.org
Redefined chart library built with React and D3
-
statnet statnet.org
-
networkD3 christophergandrud.github.io
-
Cascalog cascalog.org
data processing and querying library.
-
RocksDB rocksdb.org
embeddable persistent key-value store for fast storage based on LevelDB.
-
InfluxDB influxdata.com
a time series database with optimised IO and queries, supports pgsql and influx wire protocols.
-
graph-tool graph-tool.skewed.de
an efficient Python module for manipulation and statistical analysis of graphs (a.k.a. networks).
-
Hevo hevodata.com
No-code, fully automated data pipeline platform that supports extensive integrations, simplifying complex data workflows.
-
Glue aws.amazon.com
serverless fully managed extract, transform, and load (ETL) service
-
H2O h2o.ai
Fast statistical, machine learning & math runtime.
-
RancherOS rancher.com
RancherOS is a tiny Linux distro that runs the entire OS as Docker containers.
-
Zoomdata zoomdata.com
Big Data Analytics.
-
Yahoo Gridmix3 yahoohadoop.tumblr.com
Hadoop cluster benchmarking from Yahoo engineer team.
-
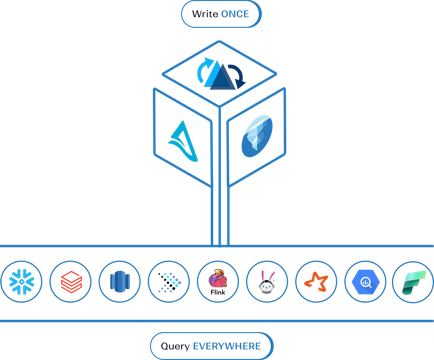
Apache XTable xtable.apache.org
incubating Apache project for interoperability across lakehouse table formats.
-
RecDB www-users.cs.umn.edu
Open Source Recommendation Engine Built Entirely Inside PostgreSQL.
-
IBM Netezza www-01.ibm.com
high-performance data warehouse appliances.
-
Google Borg wired.com
job scheduling and monitoring system.
-
Facebook Prism wired.com
multi datacenters replication system.
-
Trafodion wiki.trafodion.org
enterprise-class SQL-on-HBase solution targeting big data transactional or operational workloads.
-
Lustre file system wiki.lustre.org
high-performance distributed filesystem.
-
Apache MapReduce wiki.apache.org
programming model for processing large data sets with a parallel, distributed algorithm on a cluster.
-
Apache Whirr whirr.apache.org
set of libraries for running cloud services.
-
WebScaleSQL webscalesql.org
is a collaboration among engineers from several companies that face similar challenges in running MySQL at scale.
-
WebDataRocks webdatarocks.com
free web pivot table component for embedding analytics in applications.
-
Weaviate weaviate.io
open-source vector database for semantic search with structured filtering.
-
Wallaroo wallaroolabs.com
The ultrafast and elastic data processing engine. Big or fast data - no fuss, no Java needed.
-
Cheetah vldbarc.org
High Performance, Custom Data Warehouse on Top of MapReduce.
-
2015 vldb.org
Facebook - One Trillion Edges: Graph Processing at Facebook-Scale.
-
2012 vldb.org
Google - Processing a trillion cells per mouse click.
-
Vespa vespa.ai
is an engine for low-latency computation over large data sets. It stores and indexes your data such that queries, selection and processing over the data can be performed at serving time.
-
redpanda vectorized.io
A Kafka® replacement for mission critical systems; 10x faster. Written in C++.
-
Sibyl users.soe.ucsc.edu
System for Large Scale Machine Learning at Google.
-
2012 usenix.org
AMPLab - Fast and Interactive Analytics over Hadoop Data with Spark.
-
2013 usenix.org
Facebook - Scaling Memcache at Facebook.
-
2010 usenix.org
Facebook - Finding a needle in Haystack: Facebook’s photo storage.
-
2012 usenix.org
Microsoft - Paxos Replicated State Machines as the Basis of a High-Performance Data Store.
-
TrailDB traildb.io
an efficient tool for storing and querying series of events.
-
Apache Tika tika.apache.org
content analysis toolkit.
-
Titan thinkaurelius.github.io
distributed graph database, built over Cassandra.
-
ThingWorx thingworx.com
Rapid development and connection of intelligent systems
-
Columnar Storage the-paper-trail.org
an explanation of what columnar storage is and when you might want it.
-
Teradata teradata.com
high-performance MPP data warehouse platform.
- next page of items loading…