-
How To Stop Hating Your Tests vimeo.com
-
-
Functional Programming Design Patterns vimeo.com
-
-
Stop Writing Classes pyvideo.org
-
Is TDD Dead? martinfowler.com
-
Strategic Design infoq.com
-
Moving Past the Scaling Myth infoq.com
-
Finding a Way Out infoq.com
-
Living in a Post-Functional World infoq.com
-
DDD: putting the model to work infoq.com
-
Deconstructing Functional Programming infoq.com
-
Category Theory for the Working Hacker infoq.com
-
The Value of Values infoq.com
-
Simple Made Easy infoq.com
-
-
Are We There Yet? infoq.com
-
8 Lines of Code infoq.com
-
Ideology destroyallsoftware.com
-
Boundaries destroyallsoftware.com
-
5 WTFs in 6 LOCs brightonruby.com
-
Zoomdata zoomdata.com
Big Data Analytics.
-
Ice Bucket Challenge Data Visualization youtube.com
-
-
Designing Data Visualizations with Noah Iliinsky youtube.com
-
The beauty of data visualization youtube.com
-
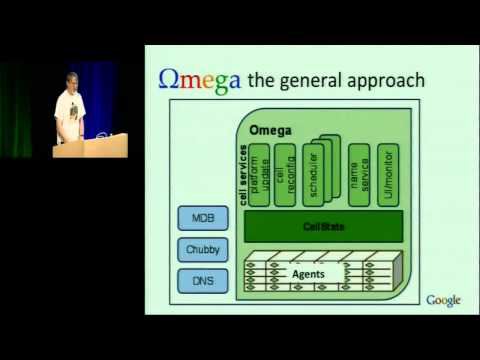
Google Omega youtube.com
job scheduling and monitoring system.
-
Yahoo Gridmix3 yahoohadoop.tumblr.com
Hadoop cluster benchmarking from Yahoo engineer team.
-
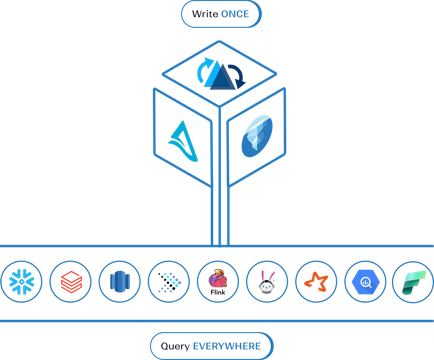
Apache XTable xtable.apache.org
incubating Apache project for interoperability across lakehouse table formats.
-
RecDB www-users.cs.umn.edu
Open Source Recommendation Engine Built Entirely Inside PostgreSQL.
-
IBM Netezza www-01.ibm.com
high-performance data warehouse appliances.
-
Google Borg wired.com
job scheduling and monitoring system.
-
Facebook Prism wired.com
multi datacenters replication system.
-
Trafodion wiki.trafodion.org
enterprise-class SQL-on-HBase solution targeting big data transactional or operational workloads.
-
Lustre file system wiki.lustre.org
high-performance distributed filesystem.
-
Apache MapReduce wiki.apache.org
programming model for processing large data sets with a parallel, distributed algorithm on a cluster.
-
Apache Whirr whirr.apache.org
set of libraries for running cloud services.
-
WebScaleSQL webscalesql.org
is a collaboration among engineers from several companies that face similar challenges in running MySQL at scale.
-
WebDataRocks webdatarocks.com
free web pivot table component for embedding analytics in applications.
-
Weaviate weaviate.io
open-source vector database for semantic search with structured filtering.
-
Wallaroo wallaroolabs.com
The ultrafast and elastic data processing engine. Big or fast data - no fuss, no Java needed.
-
Cheetah vldbarc.org
High Performance, Custom Data Warehouse on Top of MapReduce.
-
2015 vldb.org
Facebook - One Trillion Edges: Graph Processing at Facebook-Scale.
-
2012 vldb.org
Google - Processing a trillion cells per mouse click.
-
Vespa vespa.ai
is an engine for low-latency computation over large data sets. It stores and indexes your data such that queries, selection and processing over the data can be performed at serving time.
-
redpanda vectorized.io
A Kafka® replacement for mission critical systems; 10x faster. Written in C++.
-
Sibyl users.soe.ucsc.edu
System for Large Scale Machine Learning at Google.
-
2012 usenix.org
AMPLab - Fast and Interactive Analytics over Hadoop Data with Spark.
-
2013 usenix.org
Facebook - Scaling Memcache at Facebook.
-
2010 usenix.org
Facebook - Finding a needle in Haystack: Facebook’s photo storage.
- next page of items loading…